United Kingdom / journal
High-Performance Data Processing & Enterprise Transaction Systems
Design high performance data processing and enterprise transaction systems in the UK. Tips on real time processing, high throughput architecture and fault tolerance.
This article explains practical ways to design and operate high performance data processing and transaction processing architecture for enterprise data systems. It focuses on real time data processing, high throughput data architecture, fault tolerant processing systems and transaction engine design. The aim is to give clear, actionable guidance for architects, engineers and IT managers in the UK who need reliable, fast systems to process mission-critical transactions and data streams.
Why high performance data processing matters
Core principles for enterprise transaction systems
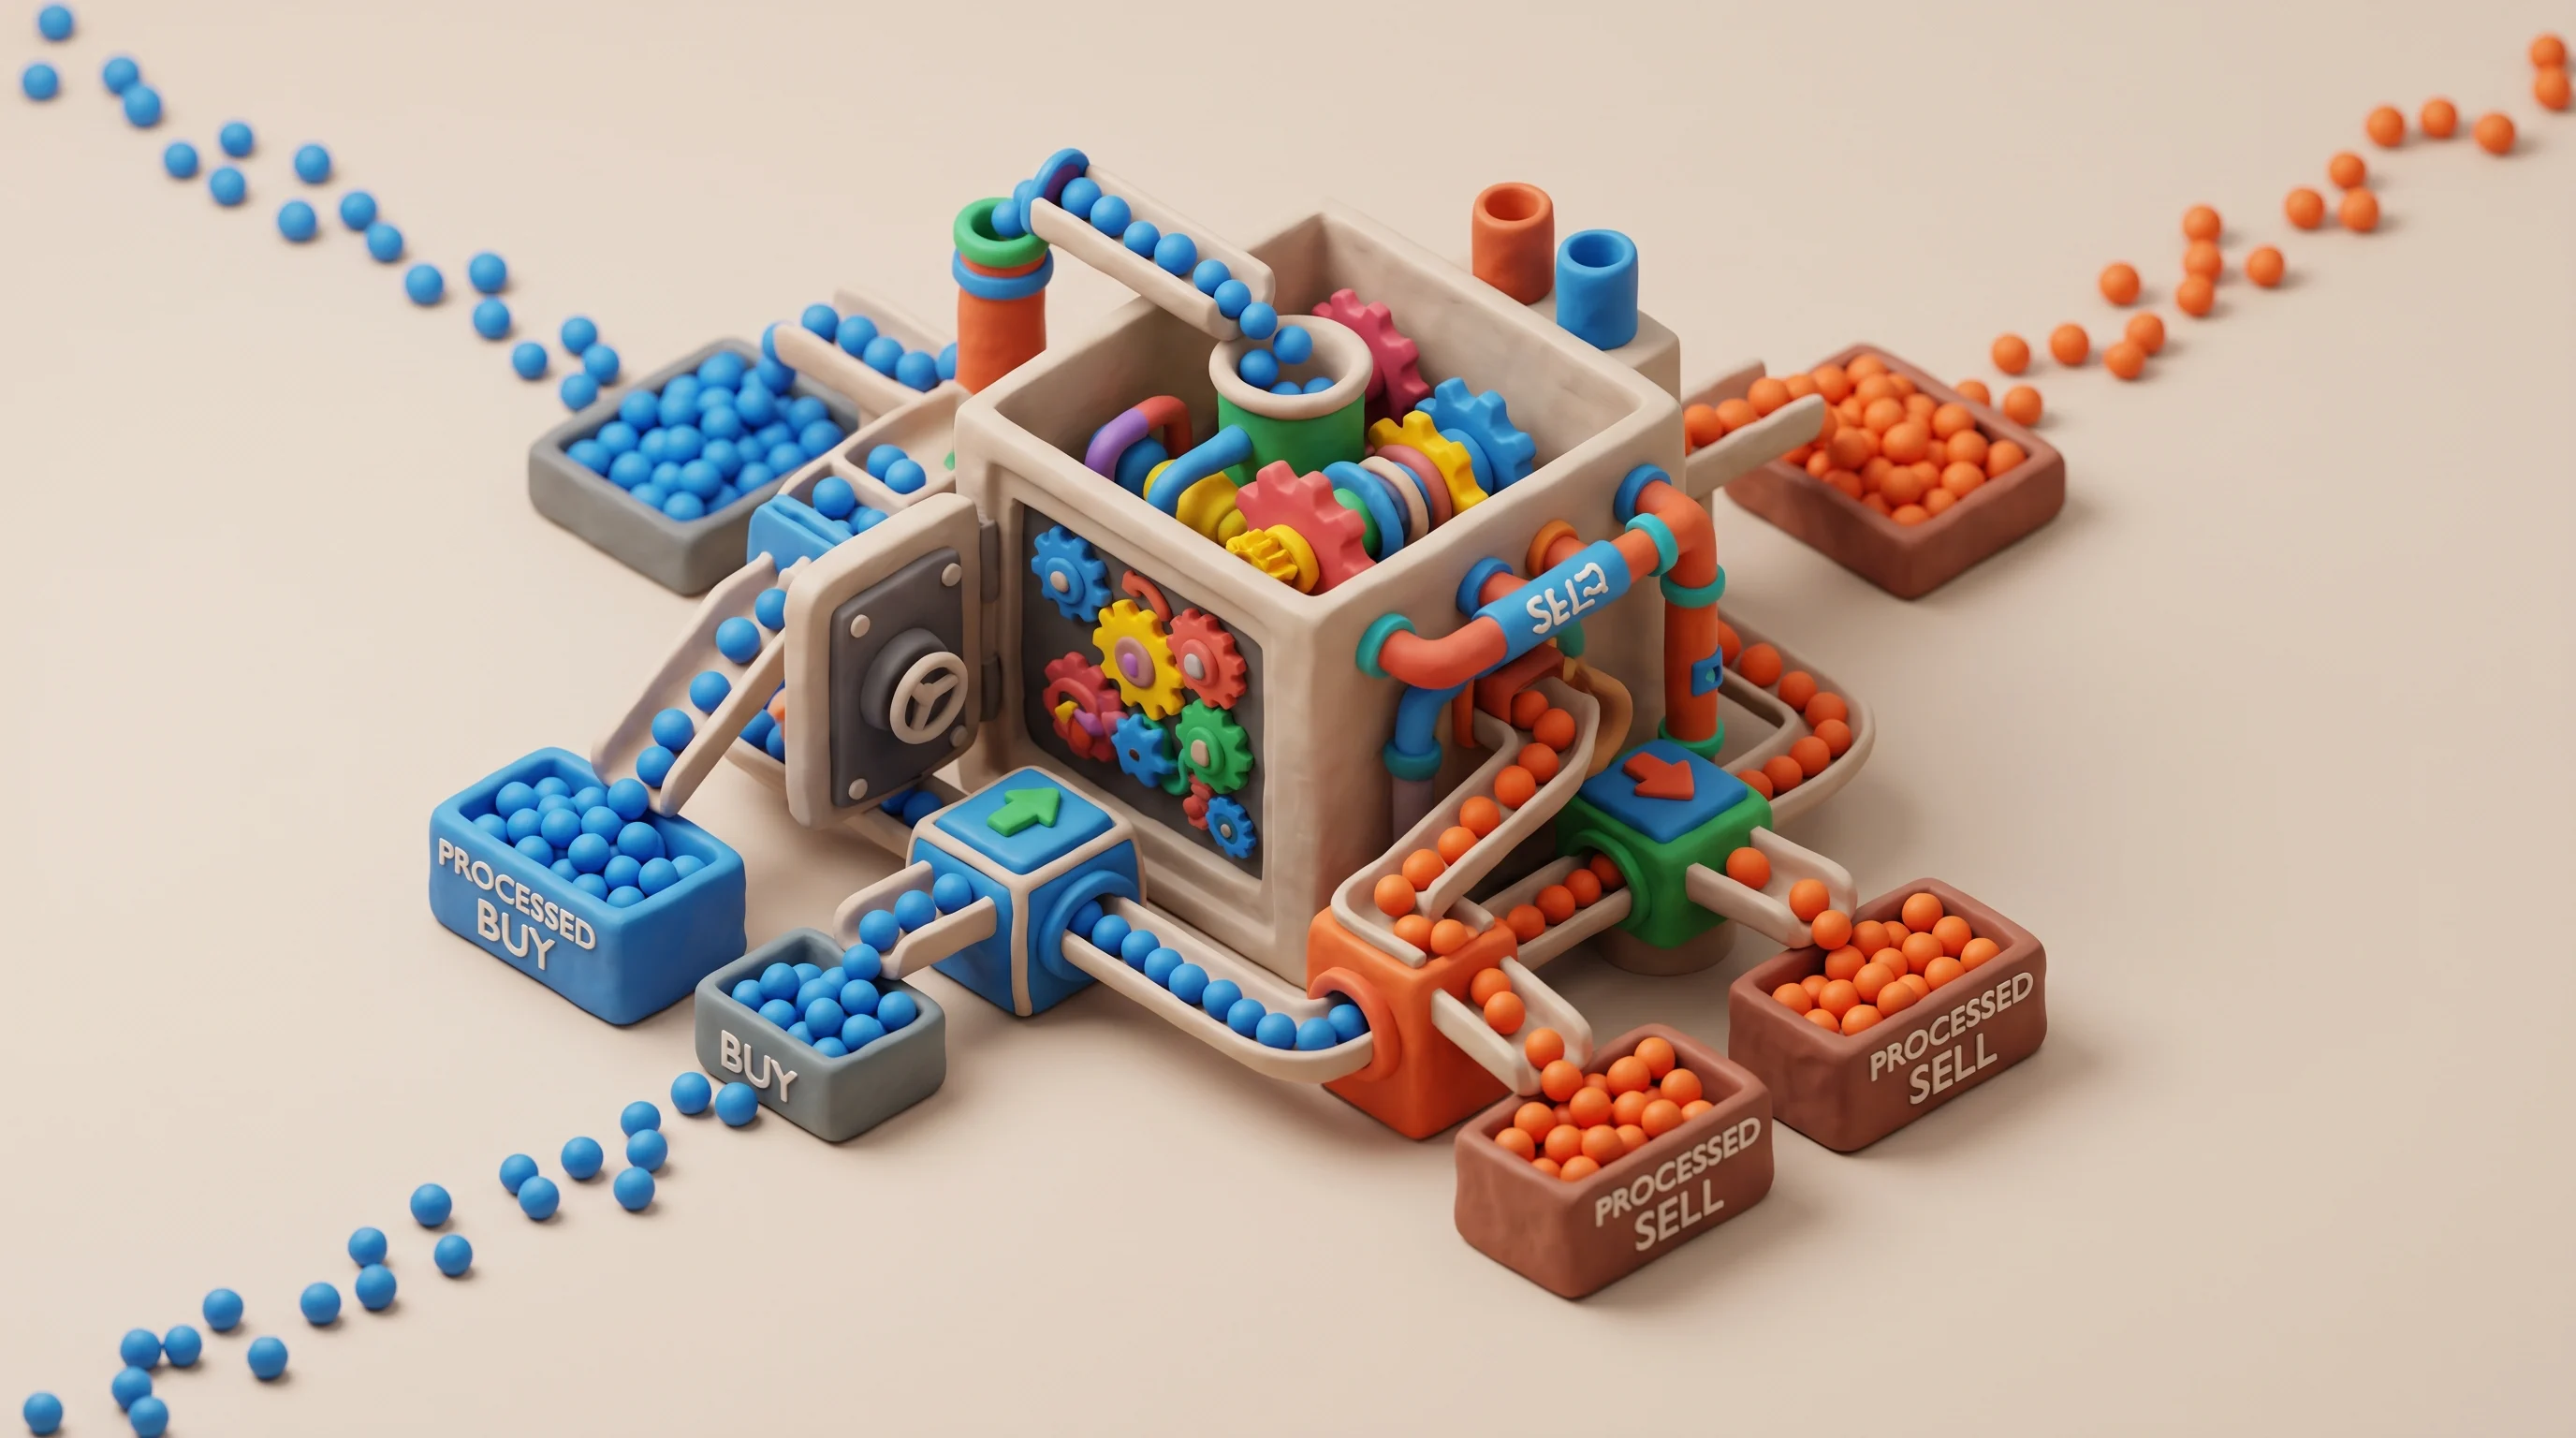
Successful systems follow a small set of principles:
- Predictable latency: Know your service-level objectives (SLOs) and design the pipeline to meet them consistently.
- High throughput: Architect for the expected peak and then some. High throughput data architecture relies on parallel processing, batching where appropriate, and removing serialization bottlenecks.
- Fault tolerance: Assume components fail. Design fault tolerant processing systems with retries, idempotency and graceful degradation.
- Data integrity: For transactions, ensure atomicity and consistency. Transaction engine design must prevent duplicates and reconcile failures.
- Observability: Instrument everything. Logs, metrics and traces are essential to spot issues quickly.
Common architecture patterns
There are tried-and-tested patterns you can combine depending on needs:
- Event-driven streaming: Use a stream platform (e.g. Kafka-like systems) to move data in real time. Streams help decouple producers and consumers and support high throughput data architecture.
- Microservices with saga patterns: Distribute transaction logic across services while managing consistency via compensating actions or orchestration.
- Command query responsibility segregation (CQRS): Separate read and write paths to optimise for throughput and latency in transaction processing architecture.
- Database sharding and partitioning: Scale writes and reads by partitioning data to avoid single-node bottlenecks.
- In-memory processing: Use caches or in-memory stores for low-latency operations where strict persistence is not required immediately.
When choosing patterns, balance complexity against business value. For many UK organisations, a simple event stream plus a robust transaction engine gives the best trade-off between speed and reliability.
Designing the transaction engine
The transaction engine is the core component that accepts requests, enforces rules, and commits state changes. Transaction engine design should focus on:
- Idempotency: Ensure operations can be retried safely. Use unique request IDs and store recent request states to avoid duplicate processing.
- Atomic operations: Keep atomic units small and clearly defined. Where cross-service atomicity is needed, use sagas or two-phase commit sparingly because they add latency and complexity.
- Concurrency control: Use optimistic or pessimistic locking depending on contention profiles. Optimistic locking works well for low conflict scenarios and scales better.
- Audit and reconciliation: Maintain immutable change logs or event streams. This makes it easier to resolve disputes and perform data workflow optimization when processes drift.
Practically, start with a reliable queue, a worker pool designed for your throughput targets, and a small, well-tested service that handles validation and commit logic. Keep the engine observable — track processing times, fail rates and queue depths.
Real time data processing strategies
- Stream-first design: Treat data as a continuous stream rather than discrete batches. Streams simplify integration and reduce end-to-end latency.
- Windowing and aggregation: Use time windows to compute metrics or rollups without blocking real time flows.
- Backpressure handling: When consumers are slower than producers, implement backpressure or use buffers with clear overflow policies.
- Hybrid models: Combine real time processing for critical paths with batch processing for heavy analytical workloads.
Remember: "real time" is relative. Define acceptable staleness and design the pipeline around that. A streaming approach often provides the best mix of speed and resilience for enterprise data systems.
Scaling for high throughput
High throughput data architecture requires horizontal scaling and careful resource planning. Techniques include:
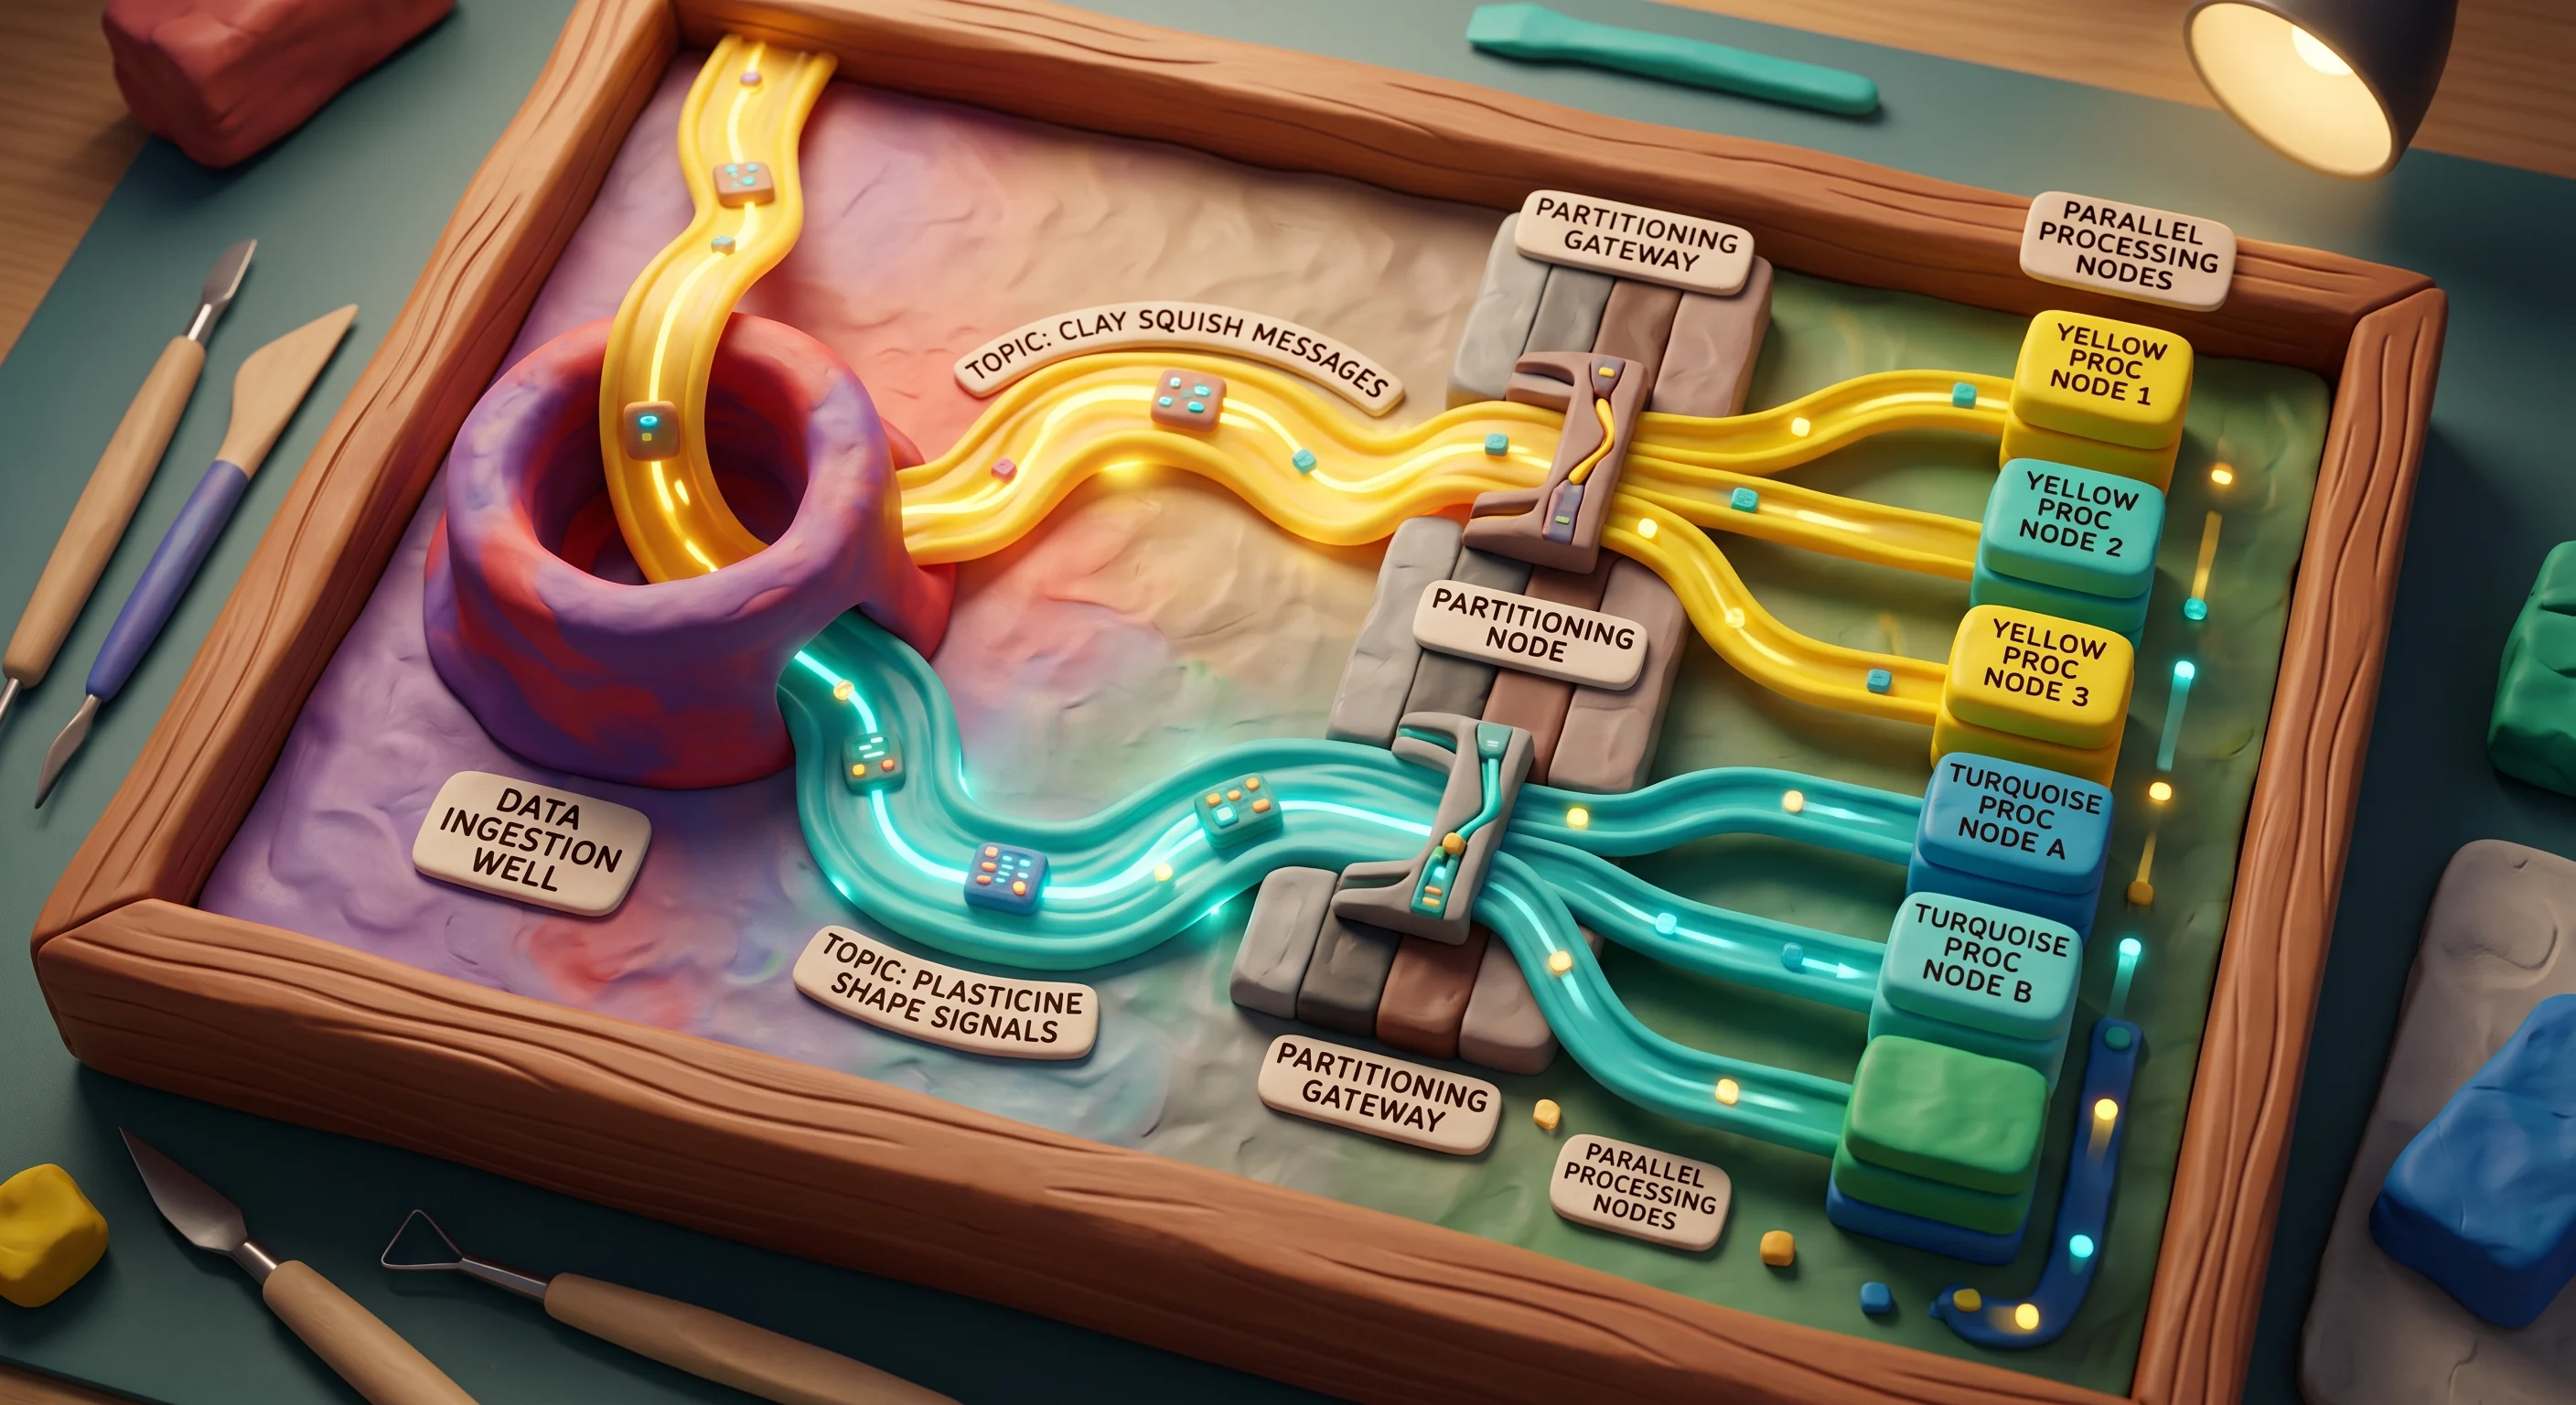
- Partitioning topics and data: Spread data across partitions so consumers can process in parallel without contention.
- Stateless workers: Make processing nodes stateless where possible; store state in fast external stores to enable scaling and quick restarts.
- Autoscaling and chaos testing: Use autoscaling policies for traffic spikes and regularly run failure drills to test scaling behavior.
- Batching and compression: Group small messages where latency allows, and use compression for network and storage savings.
Test with realistic workloads. Synthetic load tests are useful but can miss patterns like bursty traffic or multi-tenant interference. Monitoring queue lag, CPU, memory and network usage will show whether your architecture delivers the required throughput.
Building fault tolerant processing systems
Fault tolerance is about surviving partial failures without losing data or violating invariants. Best practices include:
- Redundancy: Deploy critical components across availability zones and use replicas for stateful stores.
- Graceful degradation: Prioritise critical flows when the system is under pressure, and defer or shed non-essential work.
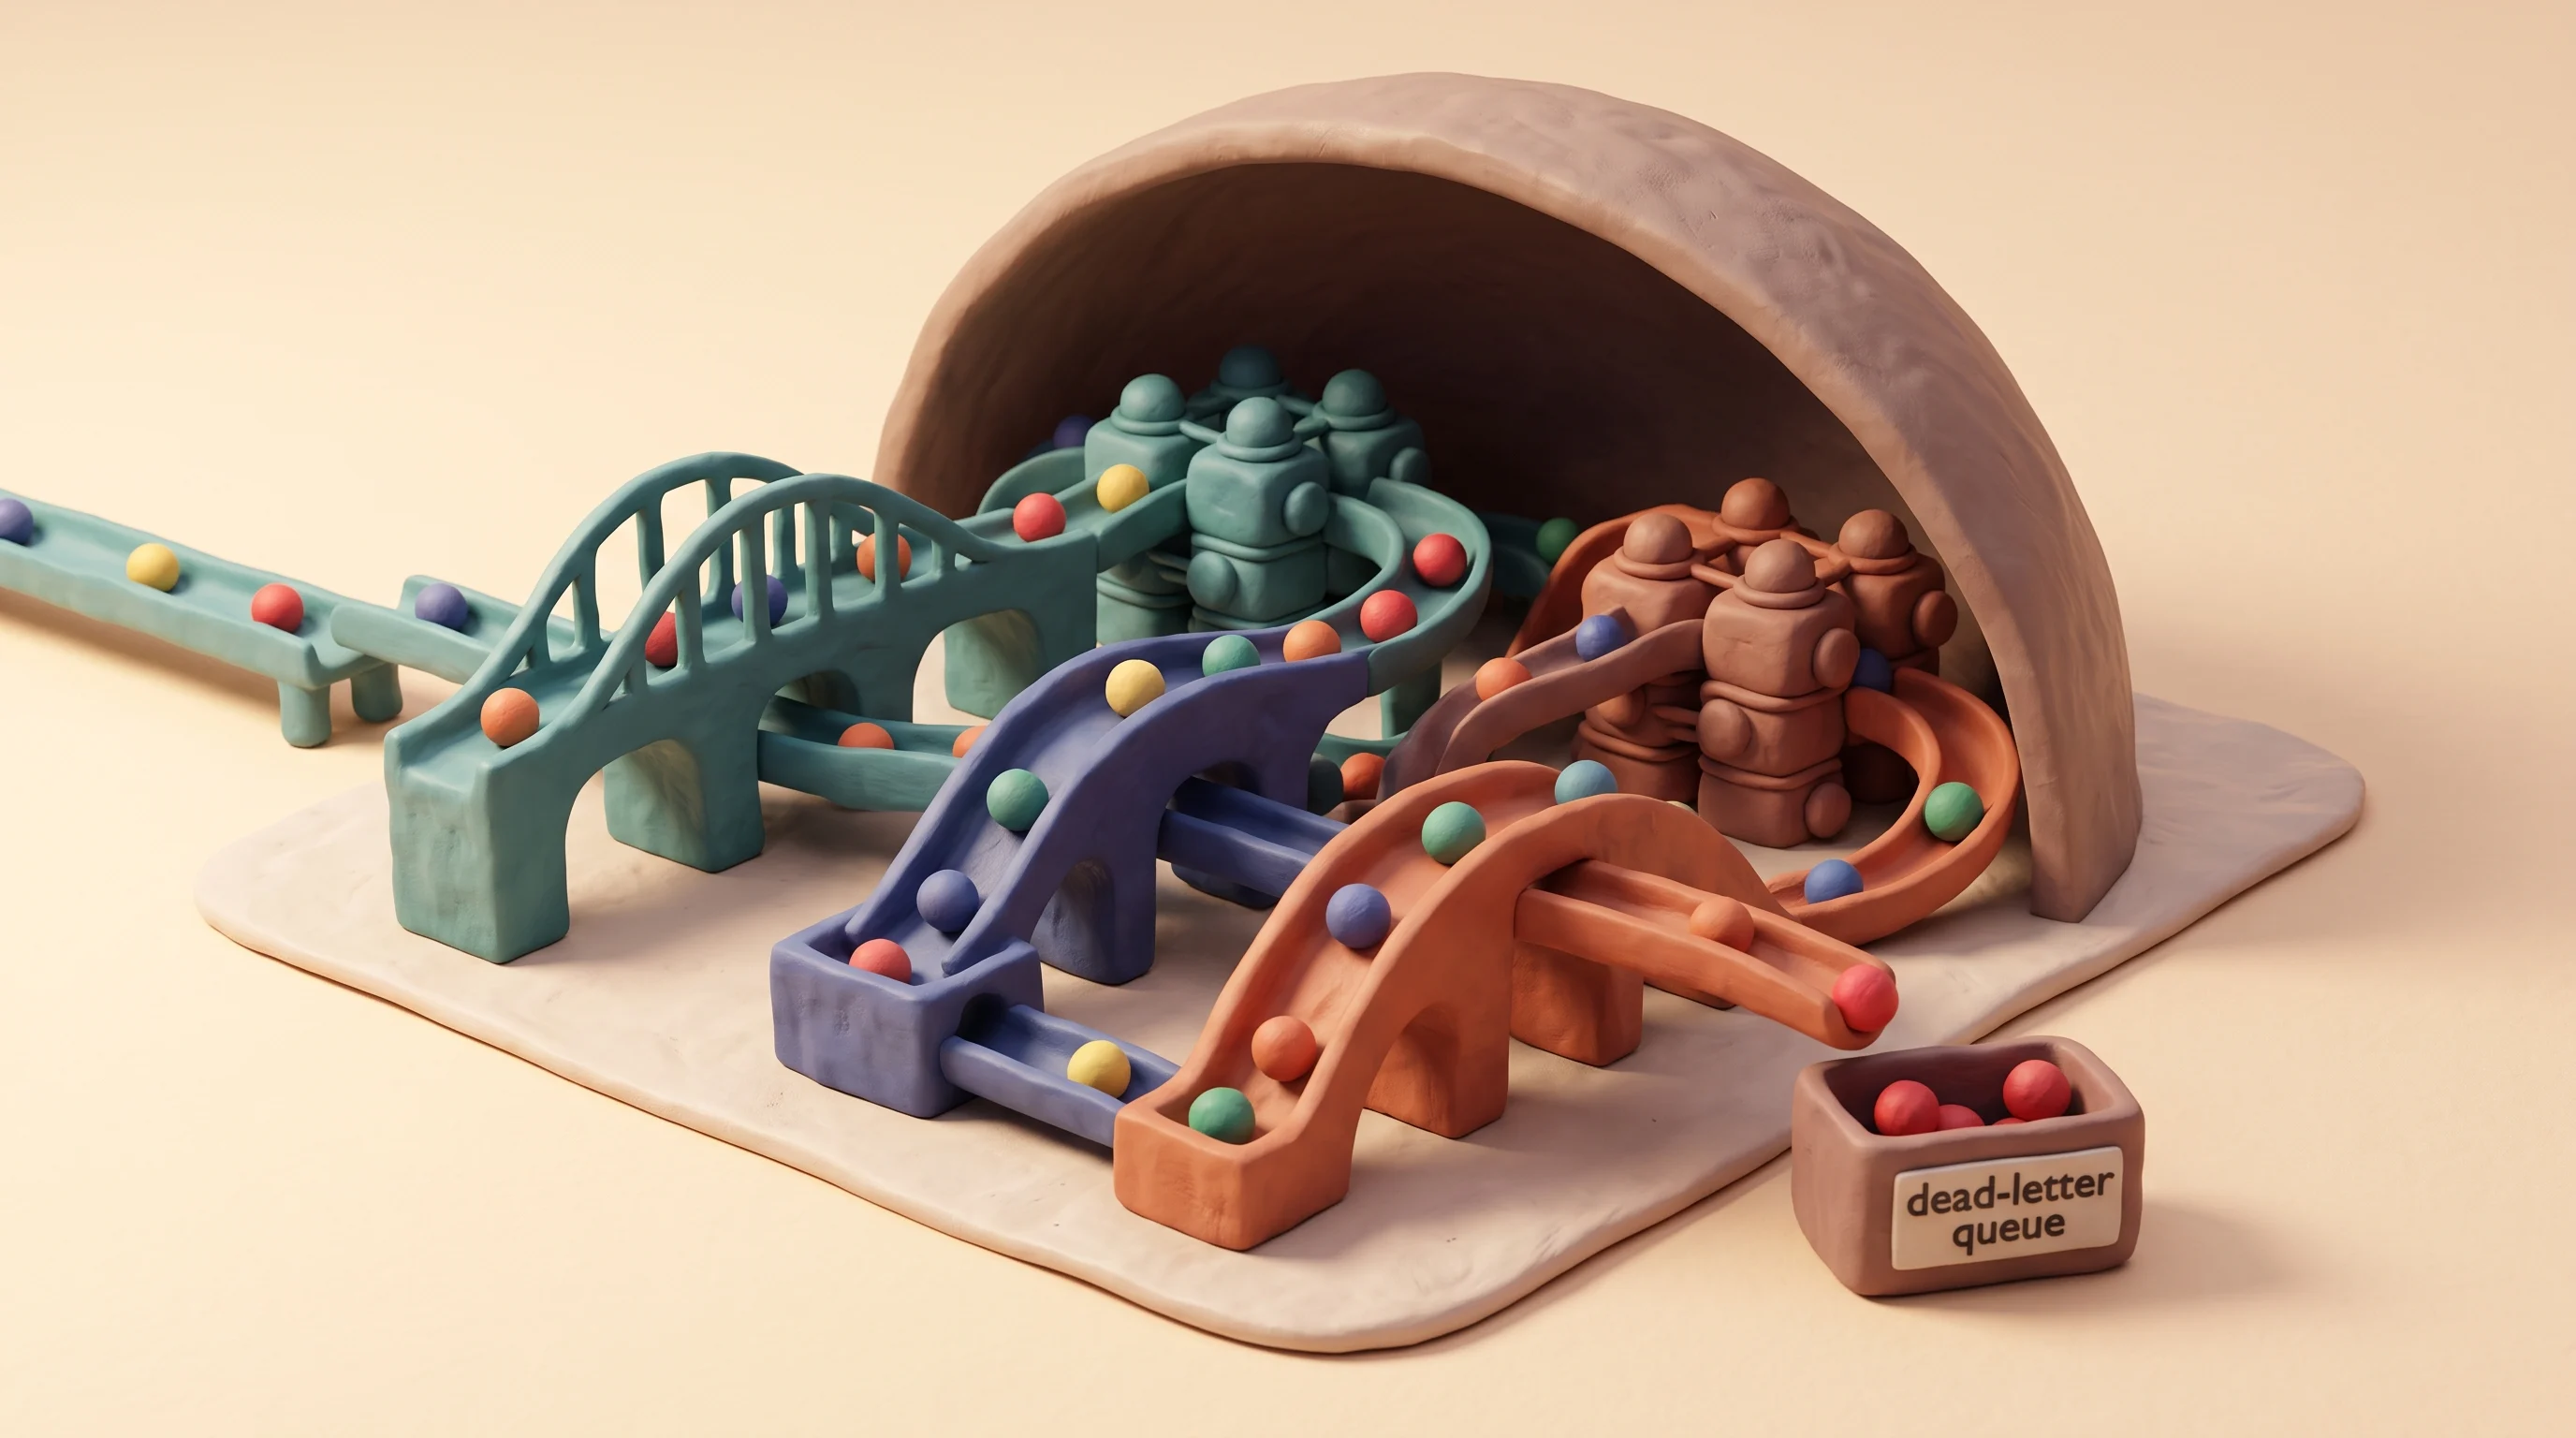
- Retry and dead-letter queues: Implement exponential backoff retries and move irrecoverable messages to a dead-letter queue for manual review.
- Idempotent consumers: Ensure consumers can safely reprocess messages to handle retries and crashes.
- Recovery procedures: Automate failover and rebuilds, and keep runbooks for manual recovery steps.
Combine these techniques with strong monitoring and alerting. Detecting anomalies early reduces recovery time and limits customer impact. Investing in fault tolerant processing systems pays off when things inevitably go wrong.
Data workflow optimization and operational tips
Optimising workflows increases efficiency and lowers costs. Focus on these operational areas:
- Profiling and hotspots: Use profiling tools to find slow paths or hot resources and optimise SQL, code, or network calls accordingly.
- Schema evolution: Design data models that can evolve without breaking consumers. Use schema registries and backward-compatible changes.
- Testing pipelines: Include integration tests for the whole workflow, not just unit tests. Use replayable recordings of production traffic for realistic tests.
- Cost control: Monitor cost per transaction and tune batch sizes, retention policies, and compute footprints to match business needs.
- Cross-team contracts: Define clear APIs and SLAs between teams so changes don’t ripple unpredictably through the system.
Simple operational improvements — better monitoring dashboards, focused tests, and automated deployment pipelines — often deliver the largest gains in throughput and reliability.
Implementation checklist and quick wins
Before a full redesign, try these quick wins:
- Measure current latency and throughput to set baselines.
- Introduce streaming for high-change data flows and keep batch for heavy analytics.
- Make critical handlers idempotent and add request IDs.
- Use partitioning to parallelise hot workloads.
- Set up alerting for queue lag and error rates.
- Run capacity tests that mirror production traffic patterns.
These steps address common bottlenecks in transaction processing architecture and help you move toward a resilient, high performance system without a complete overhaul.
FAQ — common questions about high-performance data processing
What is the difference between real time and near real time processing?
Real time typically means processing with very low latency suitable for immediate responses—often milliseconds to a few seconds. Near real time allows a small delay, like seconds to minutes, and can use lightweight batching. Choose what matches business needs and set clear SLOs.
How do I choose between a relational database and a stream store?
Use relational databases for complex transactions requiring ACID guarantees within a single database. Stream stores are better for event-driven, high throughput scenarios where you need durable, replayable logs and loose coupling between services. Often both are used together.
How do I make transaction processing fault tolerant?
Design idempotent operations, use retries with exponential backoff, replicate critical state, and implement dead-letter queues. Keep small atomic units of work and plan for graceful degradation under stress.
What is a realistic throughput target for enterprise systems?
Targets vary widely by domain. Define throughput in terms of peak transactions per second, average latency, and acceptable error rates. Base targets on business traffic profiles and test them with realistic load patterns.
How can I reduce the cost of a high throughput architecture?
Optimize retention for streams, batch non-critical work, right-size compute, and use autoscaling. Monitor cost per transaction and identify inefficiencies like excessive polling or expensive synchronous calls.
Where should I start when upgrading legacy systems?
Begin with measurement and small, low-risk changes: add observability, make critical paths idempotent, and introduce streaming for the most change-prone data. Iterate and replace components incrementally while keeping business continuity.